🚀 Supercharge your YouTube channel's growth with AI.
Try YTGrowAI FreePandas read_csv(): Read a CSV File into a DataFrame

Data saved as a CSV (comma-separated values) file is plain text until you load it into something Python can work with. pandas read_csv() reads the file into a DataFrame, a table with labeled rows and columns.
In this piece, I’ll load a sample sales.csv and show how to control the column types pandas picks.
What pandas read_csv returns
pandas.read_csv() reads a comma-separated values (CSV) file into a DataFrame, a table with labeled columns and rows. Each source record becomes a row. The header supplies the column names unless you choose another header setting.
A CSV stores text, so pandas must decide whether each field should become a number or remain text. In the sales.csv example, that decision turns the product code 00123 into the integer 123, even though both reads return a valid table.
| Default behavior | Consequence for this file |
|---|---|
| Comma separator | Each record splits into six fields |
| First row is the header | sku and fruit become column names |
| Inferred column types | Product codes lose their leading zeroes |
| Empty fields are missing | The blank stock value becomes NaN |
Choose numeric types for quantities you calculate with and string types for identifiers you compare or join on. The read_csv API reference documents these defaults and the options that change them.
Prerequisites for the CSV examples
You need Python and pandas in the same environment, plus permission to read and create the example files. I ran the programs on Linux with Python 3.14.7 and pandas 3.0.6, using a fresh virtual environment.
Install pandas with the interpreter that runs your scripts, using an isolated environment as recommended by the pandas installation guide so these dependencies stay separate from other projects.
python3 -m pip install --upgrade pandas
- Save each Python example under the filename shown beside it.
- Keep sales.csv beside the scripts, because they locate it relative to their own file path.
Path(__file__).with_name(“sales.csv”) chooses the CSV beside the saved script, regardless of your terminal’s working directory. In a notebook, use a path from the notebook’s working directory because a notebook cell does not define __file__.
Step 1: Load sales.csv into a DataFrame
Save the following text as sales.csv, keeping the product codes’ leading zeroes and the plum record’s empty stock field so you can see how pandas interprets both kinds of data.
sku,fruit,quantity,price,ordered_at,stock
00123,pear,4,1.25,2026-09-23,10
00042,plum,2,2.50,2026-09-24,
00900,peach,8,1.75,2026-09-25,3
Save this program as load_sales.py and run it from your environment. Passing a Path to read_csv loads the file. The to_string(index=False) call prints the complete small table without the automatically assigned row labels.
from pathlib import Path
import pandas as pd

path = Path(__file__).with_name("sales.csv")
df = pd.read_csv(path)
print(df.to_string(index=False))
print("shape:", df.shape)
print("sku values:", df["sku"].tolist())
print("missing stock:", int(df["stock"].isna().sum()))
python3 load_sales.py
The table has shape (3, 6), which means it contains three records and six columns. The sku list is [123, 42, 900], and the missing-stock count is 1 because pandas inferred integers for the codes and recognized the empty cell.
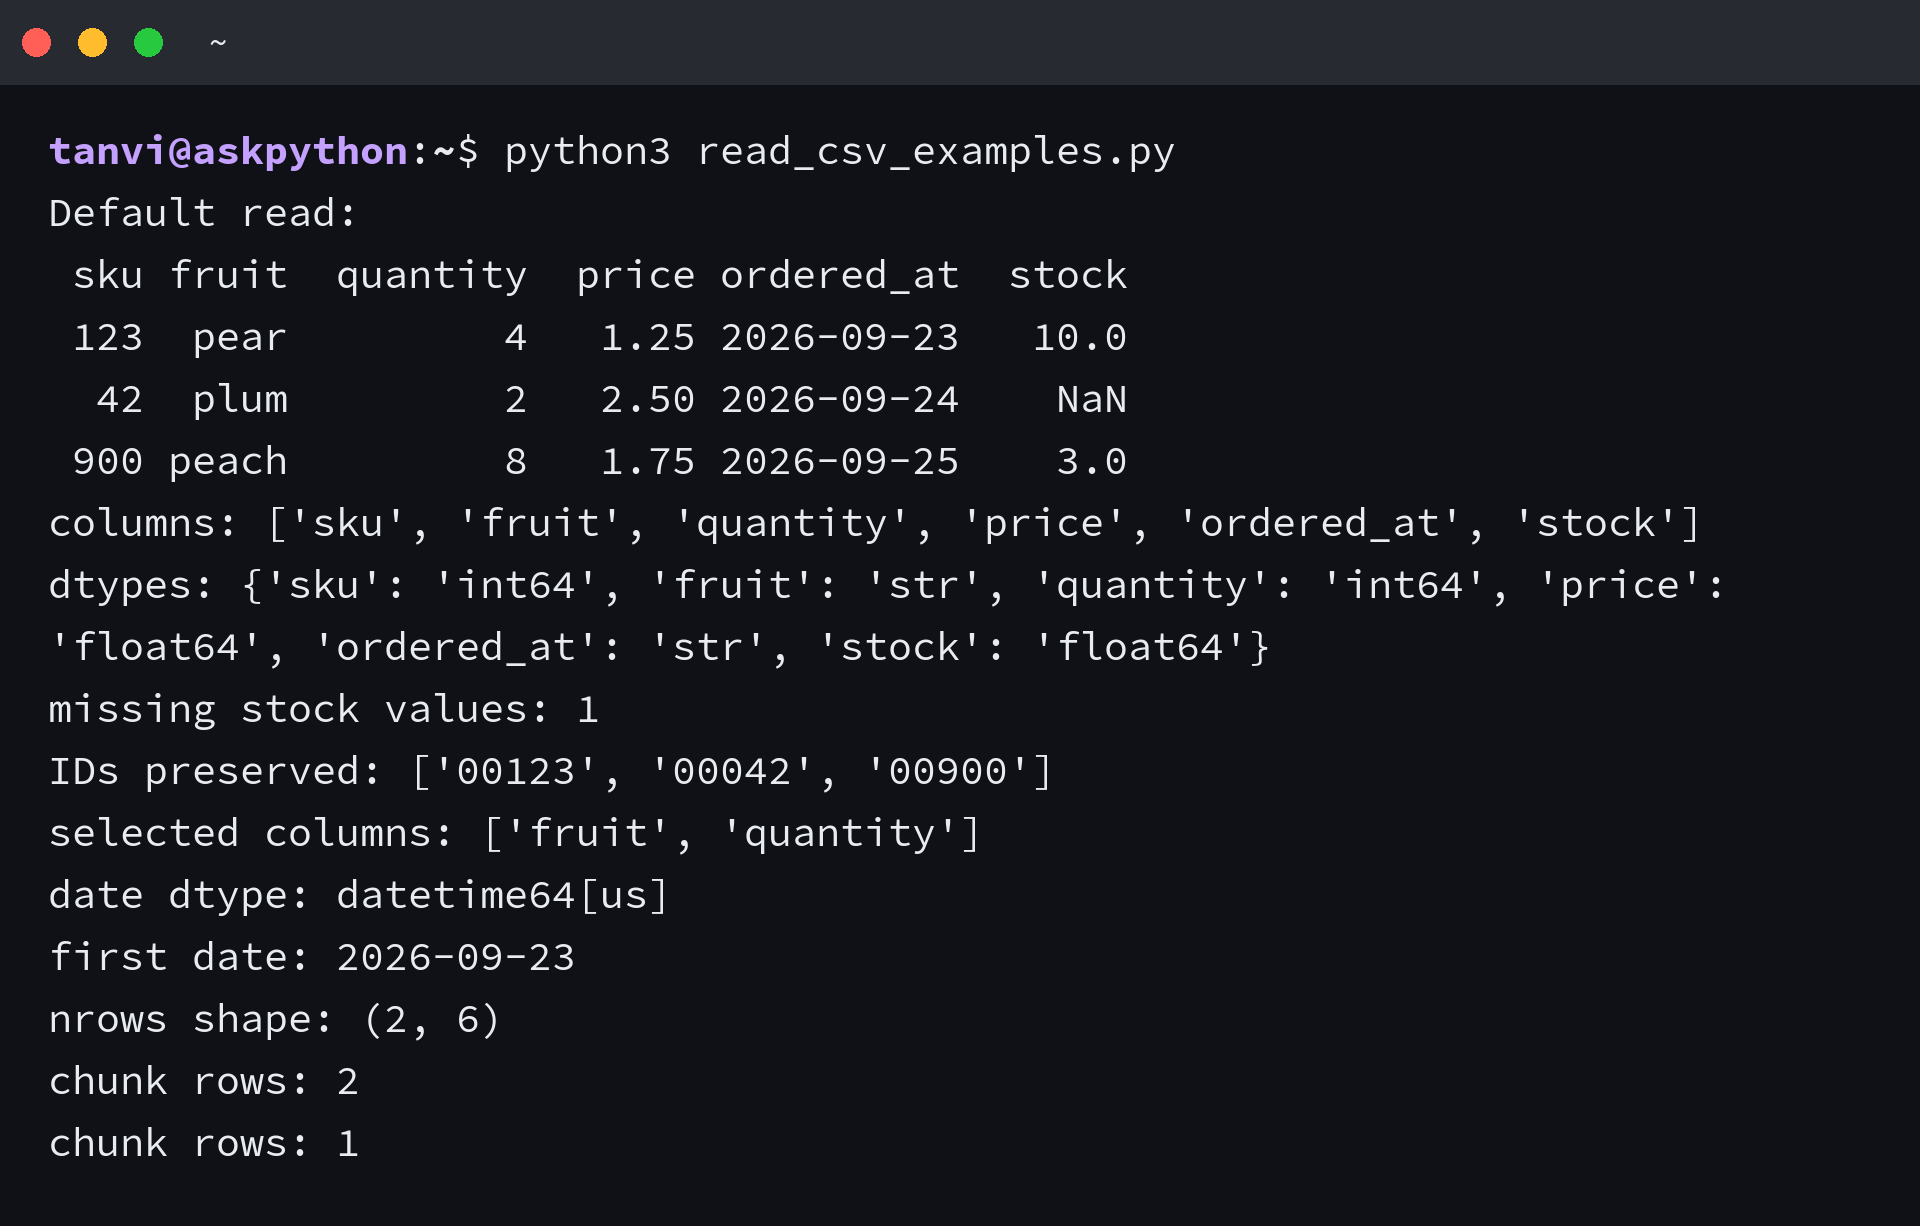
I loaded the same file with and without a string dtype, and only the string read retained 00123. The screenshot also includes the date and chunk results explained in the following tasks, so compare the default table with the preserved identifiers before using the codes as keys.
Step 2: Set the header and separator
A headerless file needs header=None, otherwise its first record becomes column labels and disappears from the data rows. Supply names when you want meaningful labels instead of automatically assigned integer column names.
Save read_csv_options.py to create and read a headerless fixture, then a pipe-delimited fixture. The first read declares both the labels and the identifier type, and the second sets sep to the character separating the fields.
from pathlib import Path
import pandas as pd

base = Path(__file__).parent
headerless = base / "headerless.csv"
headerless.write_text("00123,pear,4\n00042,plum,2\n", encoding="utf-8")
print("headerless:")
records = pd.read_csv(headerless, header=None, names=["sku", "fruit", "quantity"], dtype={"sku": "str"})
print(records.to_string(index=False))
print("header row became data:", records.iloc[0, 0] == "00123")

pipe = base / "sales-pipe.csv"
pipe.write_text("fruit|quantity\npear|4\nplum|2\n", encoding="utf-8")
print("custom separator:")
print(pd.read_csv(pipe, sep="|").to_string(index=False))
python3 read_csv_options.py
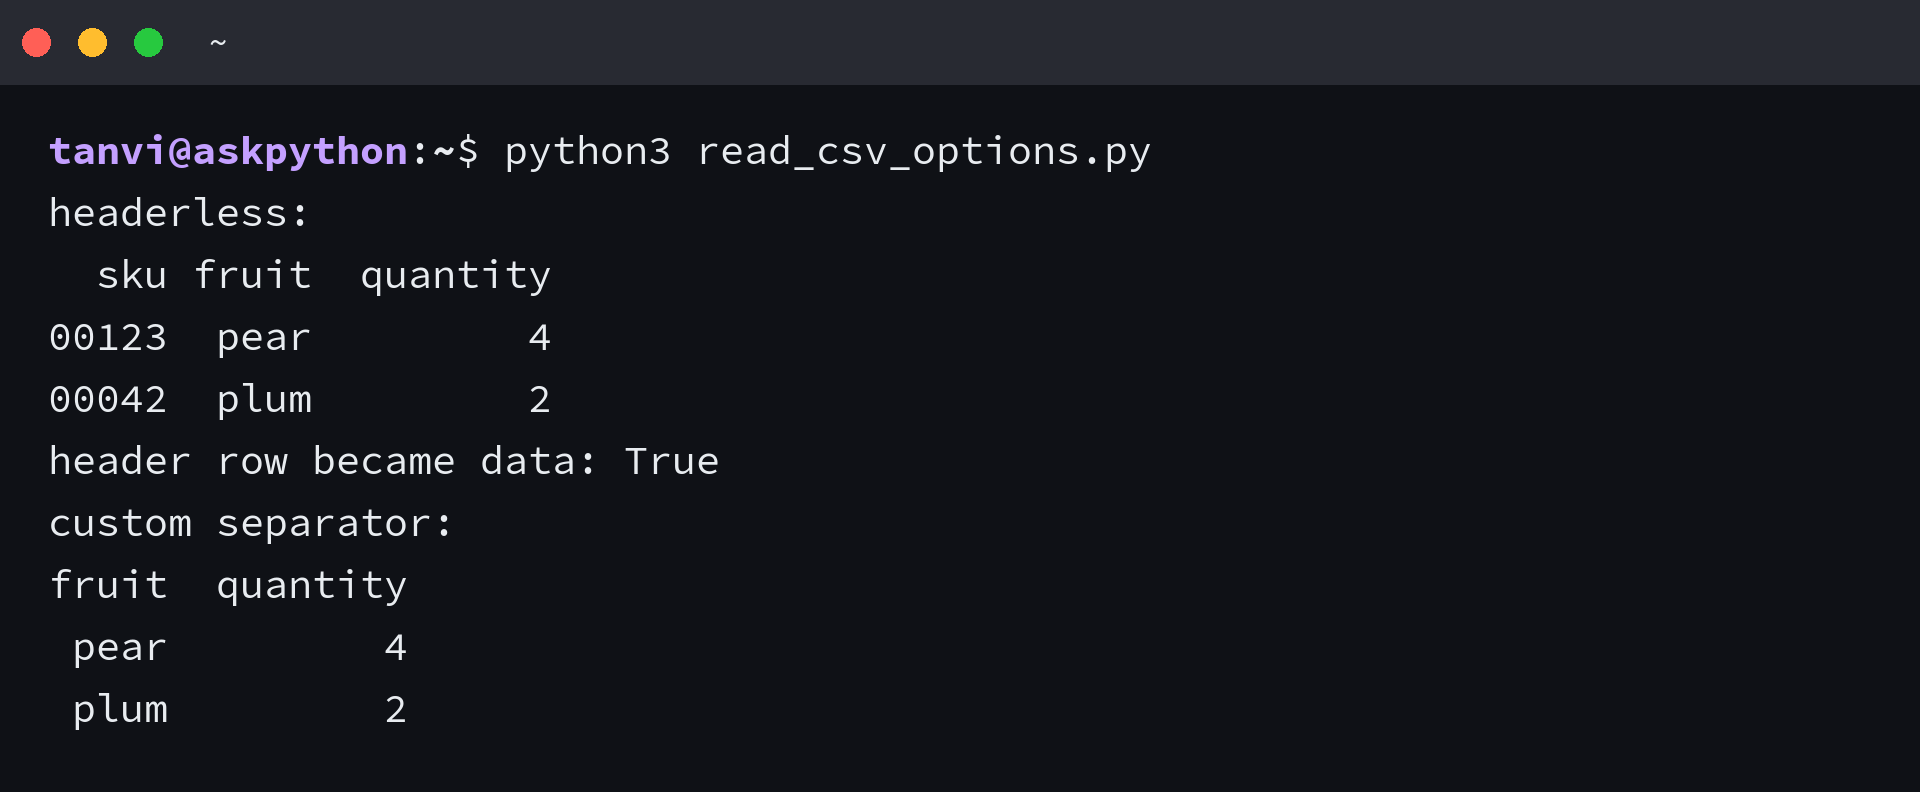
The output retains both headerless records because header=None prevents pandas from consuming a data row as names. A pipe-separated line read with the default comma separator would remain a single field, so changing the filename extension cannot fix the split.
| Source layout | Import choice |
|---|---|
| Header on the first line | Keep the default header inference |
| Every line contains data | Set header=None and supply names |
| Notes before the header | Use skiprows for the note lines |
| Fields separated by a pipe | Set sep=”|” |
When you supply names for a file that already has a header, set header=0 to replace that header rather than loading it as data. For dedicated examples, use the guides to CSV headers and custom delimiters.
Step 3: Preserve identifiers and parse dates
Set dtype before pandas converts identifier text into numbers, because converting 123 back to a string cannot recover the lost zeroes. The stock field also needs an explicit choice if you want integers with missing entries rather than a floating-point column.
Save read_csv_schema.py. The string dtype preserves sku, and the nullable Int64 dtype stores the blank stock entry as <NA> while keeping the nonmissing stock values as integers.
from pathlib import Path
import pandas as pd

path = Path(__file__).with_name("sales.csv")
df = pd.read_csv(
    path,
    dtype={"sku": "str", "stock": "Int64"},
    parse_dates=["ordered_at"],
    date_format="%Y-%m-%d",
)
print("IDs:", df["sku"].tolist())
print("stock:", df["stock"].tolist())
print("stock dtype:", df["stock"].dtype)
print("date dtype:", df["ordered_at"].dtype)
print("first date:", df.loc[0, "ordered_at"].date())
python3 read_csv_schema.py
The identifier list is [“00123”, “00042”, “00900”], and stock is [10, <NA>, 3]. parse_dates requests date conversion for ordered_at, while date_format tells the parser how to interpret the source text.
For this file, the date column becomes datetime64[us] and its first date is 2026-09-23. Inspect the resulting dtype if a source contains inconsistent dates. The API documents that an unparseable date column can remain unconverted.
Keep text identifiers separate from missing markers
A string dtype still allows pandas to recognize missing-value markers. If NA is a valid identifier, disable the default markers and define missing tokens only for the columns that need them.
Save read_csv_missing.py for a separate in-memory fixture. StringIO presents CSV text as a file-like input, and the column-specific na_values setting converts unknown in stock without discarding the identifier NA.
from io import StringIO
import pandas as pd

text = "sku,stock\nNA,unknown\n00123,10\n"
df = pd.read_csv(
    StringIO(text),
    dtype={"sku": "str", "stock": "Int64"},
    keep_default_na=False,
    na_values={"stock": ["unknown"]},
)
print(df.to_string(index=False))
print("identifier retained:", df.loc[0, "sku"] == "NA")
python3 read_csv_missing.py
The printed table retains NA in sku and shows <NA> in stock, with identifier retained: True. Disabling default markers also stops automatic blank-field recognition. Include the empty string in your chosen column’s missing-token list when your source uses blanks.
Step 4: Select columns and process chunks
Use usecols when the calculation needs only part of the file, and nrows when you want a sample of its records. For an incremental calculation, chunksize returns a TextFileReader that yields one DataFrame at a time.
Save read_csv_chunks.py to inspect a sample and then total the quantity column across the complete file. The context manager closes the reader when the loop finishes, including when processing raises an exception.
from pathlib import Path
import pandas as pd

path = Path(__file__).with_name("sales.csv")
sample = pd.read_csv(path, nrows=2, usecols=["fruit", "quantity"])
print("sample shape:", sample.shape)
print("selected columns:", sample.columns.tolist())

total = 0
with pd.read_csv(path, usecols=["quantity"], chunksize=2) as reader:
    for chunk in reader:
        print("chunk rows:", len(chunk))
        total += int(chunk["quantity"].sum())
print("total quantity:", total)
python3 read_csv_chunks.py
| Observed output | What it means |
|---|---|
| sample shape: (2, 2) | nrows limits the sample to two records, and usecols retains two fields |
| chunk rows: 2, then chunk rows: 1 | The final chunk contains the remaining record |
| total quantity: 14 | The sum includes all records, not only the sample |
I accumulated a scalar total rather than retaining the chunks. Each iteration adds its quantity sum and releases the previous table when the loop advances. On a larger source, choose a chunk size that fits your processing step and keep only the aggregate you need.
The pandas input/output guide distinguishes low_memory, which controls internal parsing but still returns a complete DataFrame without chunks, from the incremental iterator interface.
Diagnose file and parsing errors
A wrong encoding fails before pandas can interpret field separators, so changing sep cannot repair a UnicodeDecodeError. Save read_csv_errors.py to create Latin-1 bytes and attempt UTF-8 decoding. The program then reads the same file with its actual encoding.
from pathlib import Path
import pandas as pd

path = Path(__file__).with_name("latin1.csv")
path.write_bytes("fruit,quantity\ncafé,4\n".encode("latin-1"))
try:
    pd.read_csv(path, encoding="utf-8")
except UnicodeDecodeError as error:
    print(type(error).__name__ + ": " + str(error))
print("With the source encoding:")
print(pd.read_csv(path, encoding="latin-1").to_string(index=False))
python3 read_csv_errors.py
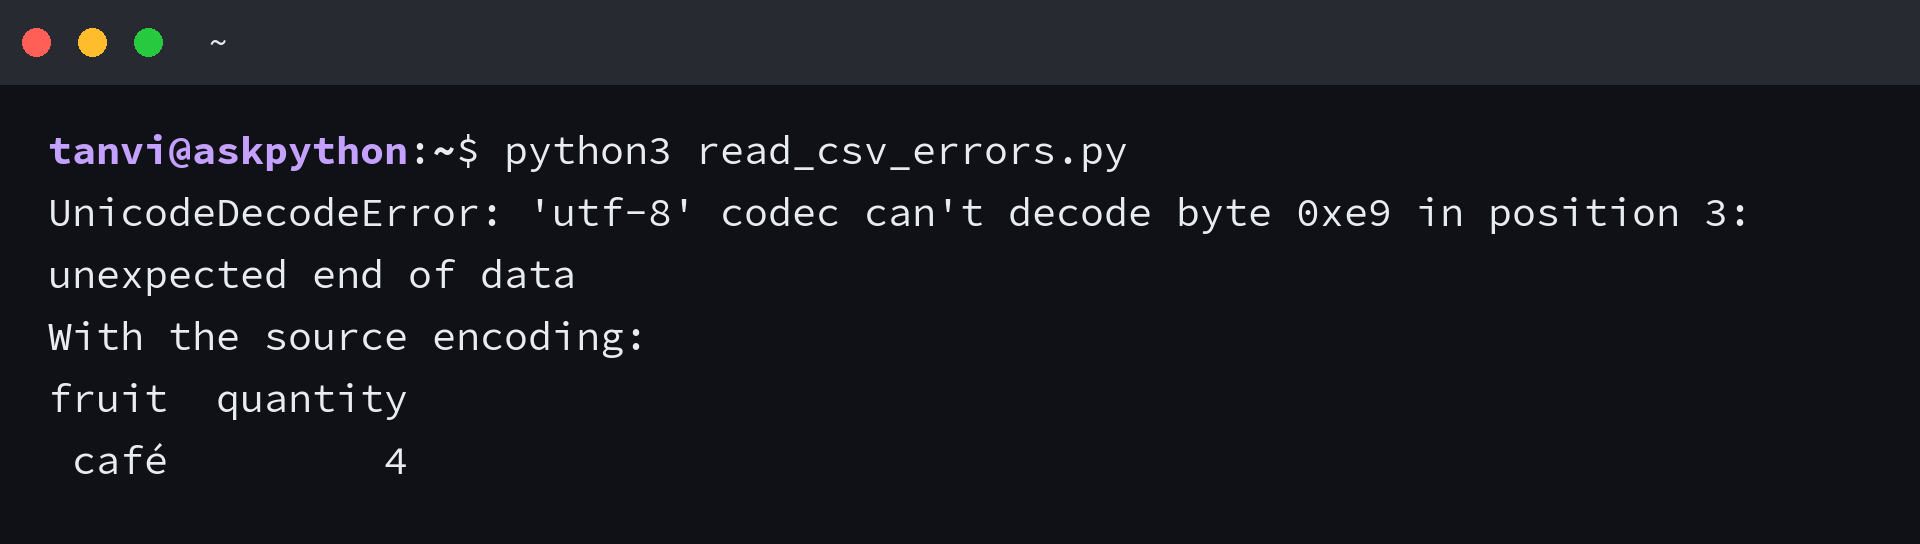
The exception identifies byte 0xe9, and the corrected read prints café with quantity 4. Use the encoding supplied by the exporter rather than guessing Latin-1, because a permissive decoder can accept bytes while producing the wrong characters.
- FileNotFoundError means the supplied path could not locate the file. Inspect the path relative to the process or script location you chose.
- An unexpected single column points to a separator mismatch. Inspect a source line and select its delimiter.
- ParserError can mean a record has more fields than expected. Inspect that record and its quoting before choosing on_bad_lines=”skip”, which discards records.
Quoted commas inside a field are handled by normal CSV quoting, so a comma within quoted text does not need a different separator. If trailing delimiters produce an unexpected index, inspect the record width and the documented index_col=False option rather than assuming the table is correctly aligned.
Validate the fields before calculating totals
For the sales fixture, a valid import keeps the codes padded and the dates converted before you calculate anything. Save validate_sales.py to turn those requirements into assertions and then calculate each line’s quantity multiplied by its price.
from pathlib import Path
import pandas as pd

path = Path(__file__).with_name("sales.csv")
df = pd.read_csv(
    path,
    dtype={"sku": "str", "stock": "Int64"},
    parse_dates=["ordered_at"],
    date_format="%Y-%m-%d",
)
assert df.shape == (3, 6)
assert df["sku"].tolist() == ["00123", "00042", "00900"]
assert int(df["stock"].isna().sum()) == 1
assert pd.api.types.is_datetime64_any_dtype(df["ordered_at"])
print("import checks passed")
print("line totals:", (df["quantity"] * df["price"]).tolist())
print("first quantity:", df.loc[0, "quantity"])
python3 validate_sales.py
The program prints import checks passed and line totals [5.0, 5.0, 14.0], followed by first quantity: 4. An assertion failure stops the calculation at the import boundary, where the field meaning can still be compared with the CSV.
Replace the fixture assertions with the requirements of your source before using this approach on another dataset. Preserve identifier text at the read call, because a join on the wrong code can succeed without raising a parser error.
CSV input questions
These questions concern the input interface and selecting a cell after the import, rather than another set of parser settings.
How do I read a specific cell from a CSV with pandas?
Read the file into a DataFrame, then select the row and column. In the sales example, df.loc[0, “quantity”] returns 4 because row label 0 identifies the first imported record.
Can I read CSV text without creating a file?
Yes, pass a StringIO object containing the CSV text to read_csv. The missing-marker example uses this interface and returns a DataFrame in the same way as a file path.
Can Python read a CSV without pandas?
Python includes a csv module for iterating through CSV records. Use pandas when you want a DataFrame and its column operations, and consult the Python csv documentation when row-by-row processing fits the task.