🚀 Supercharge your YouTube channel's growth with AI.
Try YTGrowAI FreePandas Melt and Pivot Data

A table can keep one row per record while storing each measurement in a separate column. Pandas melt turns selected measurement columns into labeled rows, and pivot reshapes those rows into columns again.
This article walks through choosing columns for melt and restoring a wide table with pivot.
TL;DR: Melt wide data into long rows
Use DataFrame.melt() to turn selected measurement columns into variable and value rows, then use DataFrame.pivot() to spread those rows back into columns when each identifier-variable pair is unique.
- Keep identifying fields in id_vars.
- Choose measurements with value_vars.
- Give the generated columns names with var_name and value_name.
- Use pivot_table() when duplicate keys need aggregation.
What does pandas melt do?
melt() turns a wide DataFrame, with measurements in columns, into long rows beside identifying fields. The ID values repeat so each measurement stays connected to its source record.
A sales table with one row per city and separate jan and feb columns becomes rows with city, month and sales.
Set id_vars to identifiers and value_vars to measurement columns. With no identifier fields, pass an empty list for id_vars to melt every column. The generated fields default to variable and value, with var_name and value_name available for custom labels.
How to melt and pivot a DataFrame step by step
This example keeps an ID and city as identifiers, reshapes two monthly measurements, then restores a wide table using the same keys. I ran the exact script shown here with pandas 3.1.0. The output follows the code.
Step 1: Select the identifier and value columns
Set the identifier fields in id_vars and measurement columns in value_vars. Use var_name and value_name to label the generated fields.
import pandas as pd

wide = pd.DataFrame({
    "city": ["Pune", "Surat", "Jaipur"],
    "id": [1, 2, 3],
    "jan": [10, 12, 9],
    "feb": [11, 15, 8],
})

long = wide.melt(
    id_vars=["id", "city"],
    value_vars=["jan", "feb"],
    var_name="month",
    value_name="sales",
)
print(long.to_string(index=False))

wide_again = long.pivot(index=["id", "city"], columns="month", values="sales")
print("\nPivoted back:")
print(wide_again.reset_index().to_string(index=False))
 id   city month  sales
  1   Pune   jan     10
  2  Surat   jan     12
  3 Jaipur   jan      9
  1   Pune   feb     11
  2  Surat   feb     15
  3 Jaipur   feb      8

Pivoted back:
 id   city  feb  jan
  1   Pune   11   10
  2  Surat   15   12
  3 Jaipur    8    9
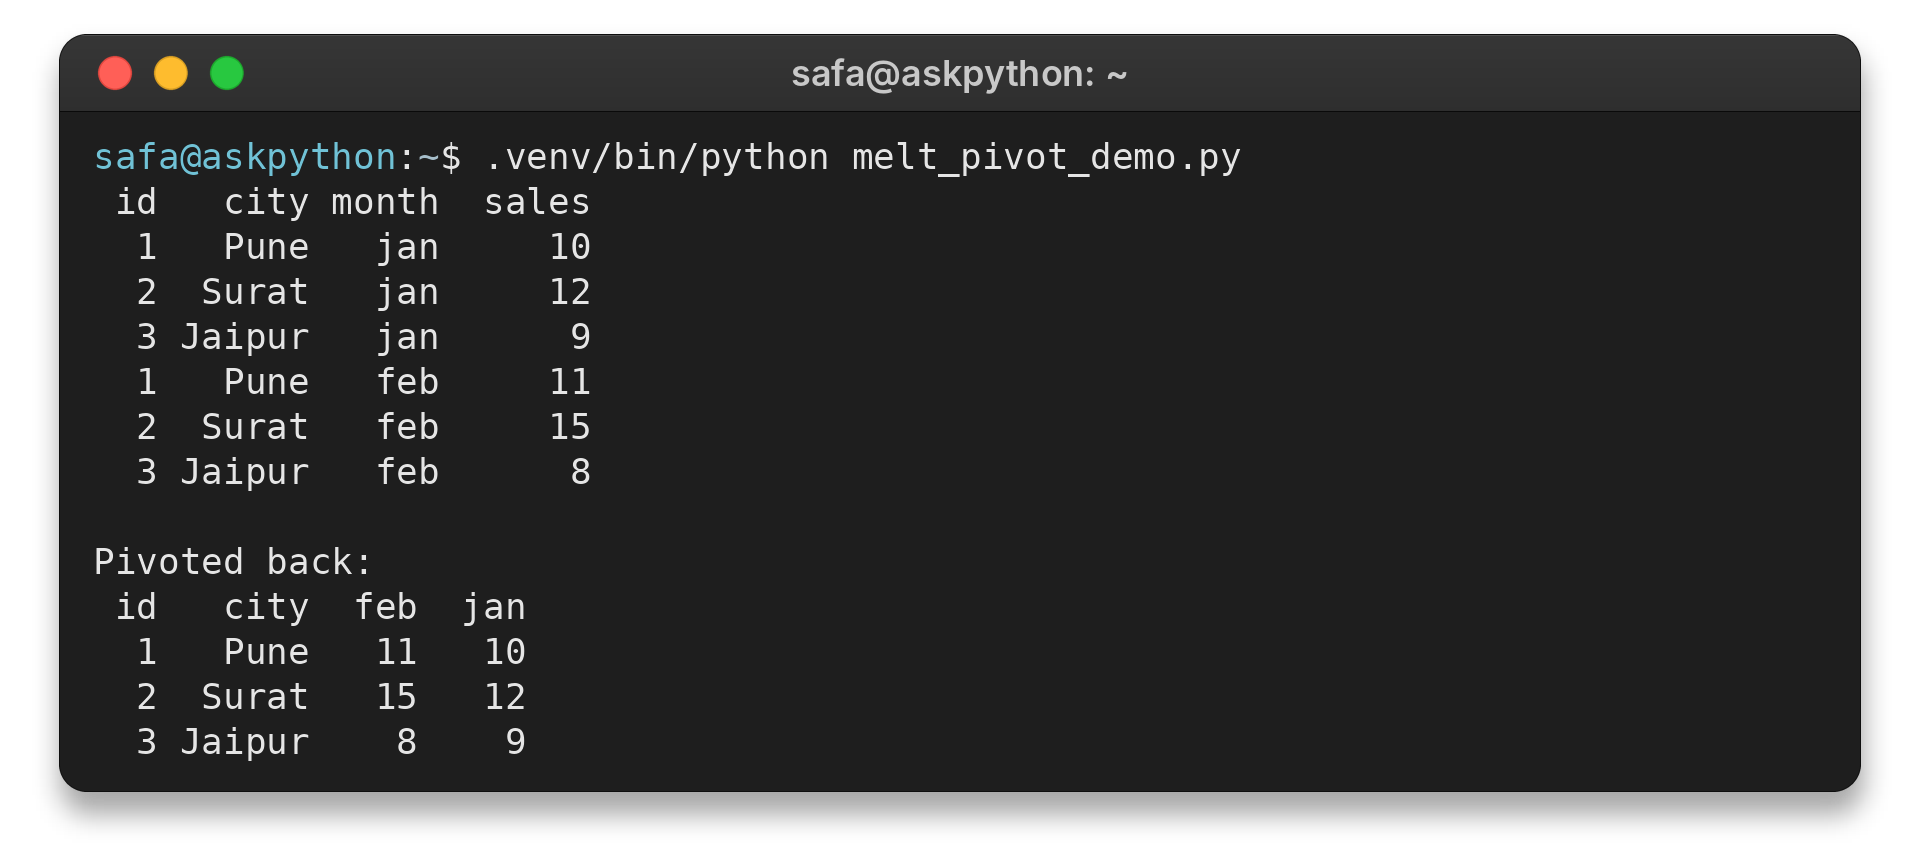
The pivoted table has one row per ID and city, with months as columns. Pandas chooses the label order. Reindex the columns when a fixed display order matters.
Use the long result to group sales by month or by month and city.
Step 2: Pivot the long rows back into columns
Call pivot() on the melted DataFrame with the ID fields in index, the variable field in columns, and the measurement field in values. Use the names created by melt, such as month and sales.
Call reset_index() when you need the ID fields as ordinary columns for export or a merge.
What should you check before pivoting back?
pivot() reshapes when each index-and-column pair has one value.
| Situation | What happens | What to do |
|---|---|---|
| Repeated identifier and month pair | pivot() raises a ValueError | Add a distinguishing key or aggregate with pivot_table() |
| Missing month for one identifier | The resulting cell is missing | Decide whether missing means unknown or should be filled |
| Original row index matters | melt() resets it by default | Use ignore_index=False to retain and repeat index labels |
| Only some measurement fields belong in output | Unlisted fields stay outside when value_vars is explicit | List the intended fields in value_vars |
For repeated measurements, use pivot_table() with an aggfunc that fits the data, such as sum for totals. Its default aggfunc is mean.
A missing cell after pivot marks an unobserved identifier-column combination. Fill it with zero only when the source definition confirms that value.
When value_name matches an input label, choose another name before melting to prevent ambiguity.
With ignore_index=False, source row labels repeat in the melted DataFrame’s index. Use reset_index() when they need to travel as ordinary columns through a later merge or export.
With N input rows and M selected value columns, melt returns N times M rows. Check that growth before reshaping a large table with many measurement columns.
If values is omitted, pivot includes all remaining fields as hierarchical columns. Specify the measurement field to control the result.
For MultiIndex columns, use col_level to melt one label level. When both levels distinguish the measurements, pass full tuple labels in value_vars so pandas retains each component in separate variable fields.
For loading a source table before reshaping, see AskPython’s guide to reading a CSV into a pandas DataFrame and its pandas module tutorial.
Conclusion: Match the shape to the next operation
Choose identifiers that preserve each observation’s meaning. The API links below document additional parameters and related operations.
For parameter details, consult the pandas melt API and pivot API.
FAQ
These short answers cover the common choices that change a melt-and-pivot result.
What are the default melt column names?
The former source column names go in variable and the corresponding cell values go in value. Use var_name and value_name to choose other labels.
Can pandas melt select specific columns?
Yes. Pass the columns to reshape in value_vars and the columns to retain as identifiers in id_vars.
Why does pivot raise a duplicate entries error?
At least one index and columns key pair has multiple values. Add another key or use pivot_table with an aggregation that fits the data.
Does melt change the original DataFrame?
melt returns a reshaped DataFrame. Assign the result to a new variable when you want to keep the wide input available too.
Can value_vars use a slice?
value_vars takes column labels. Build a list of the desired labels from the DataFrame columns and pass that list to melt.
What if pivot should combine repeated values?
Use pivot_table and set aggfunc to the statistic that matches the data, such as sum for totals or mean for averages.