🚀 Supercharge your YouTube channel's growth with AI.
Try YTGrowAI FreeThe pickle Module in Python

A value created in one Python run may still be useful after that run ends. Python’s pickle module turns an object into bytes that Python can reconstruct.
I’ll show how to save and restore a Python value with pickle, then explain when its Python-specific format is appropriate for trusted data.
TL;DR: Python pickle module
Python’s pickle module converts a Python object hierarchy into a binary stream and reconstructs it later with a matching load operation. Use it only when the data is trusted and Python-specific storage is acceptable.
- Use pickle.dump(obj, file) and pickle.load(file) for files opened in binary mode.
- Use pickle.dumps(obj) and pickle.loads(data) when the serialized bytes stay in memory.
- Never unpickle data from an untrusted or tamperable source.
What is the pickle module in Python?
The pickle module serializes a Python object hierarchy into a byte stream, then reconstructs that hierarchy from the stream. Serialization means turning a live value into a representation that can be stored or transmitted. Pickling is Python’s name for this operation.
The format is binary and Python-specific. A pickle file is not a text document that another language can reliably parse, and its bytes are not a safe substitute for a data-validation format. Pickle can preserve many Python values and object relationships that JSON does not represent directly.
The module is part of Python’s standard library, so there is nothing to install. Import it with the statement import pickle. Its four common functions form two pairs.
The dump function writes an object to a file, while dumps returns serialized bytes. The load function reads from a file, while loads reconstructs an object from bytes.
These functions are useful when a value needs to cross a boundary between program runs. A saved configuration, cached computation or local model state can be reconstructed later, provided the code and dependencies needed by its objects remain available.
A pickle does not provide database transactions or coordinate concurrent writers. A program that stores important state still needs its own backup, naming and synchronization strategy. Pickle handles conversion between Python objects and bytes, not the surrounding persistence policies.
Pickle is also not an object inspection format. Its normal representation is binary, so opening the file in a text editor is not a reliable way to understand its contents.
For inspection without executing pickle instructions, Python provides the pickletools module, which disassembles a stream for analysis. Inspection is not a reason to load an untrusted pickle.
Pickle files and object identity
A pickle stores a representation of values, not a running Python process. Loading creates objects in the current process. Pickle can preserve references shared inside one serialized hierarchy, so repeated references do not always become unrelated copies, but it does not preserve the identity of an object across separate processes.
Functions and classes are generally recorded by qualified name rather than by copying their source code. The defining module and name must be importable when the data is loaded. That is why moving or renaming a class can break an older pickle even when the saved bytes are intact.
How to save and load a Python object with pickle
A file round trip has two matching operations: write with pickle.dump(), then read with pickle.load(). Open the file with wb for binary writing and rb for binary reading.
Step 1: Choose the object and a file path
Pick a value that the module can serialize and choose a path your program is allowed to write. This example uses a dictionary of strings, a list and a Boolean. It writes a local file named sample.pickle.
Step 2: Serialize the value in binary mode
Call pickle.dump(object, file) while the file is open. The second argument is an open binary file object, not a filename string.
The optional protocol controls the byte format. Using pickle.HIGHEST_PROTOCOL selects the highest protocol supported by the running interpreter, which may be unsuitable if an older Python must read the file.
import pickle
from pathlib import Path

path = Path("sample.pickle")
record = {"user": "reader", "scores": [8, 10], "active": True}
with path.open("wb") as stream:
    pickle.dump(record, stream, protocol=pickle.HIGHEST_PROTOCOL)
with path.open("rb") as stream:
    restored = pickle.load(stream)
print(restored)
print(type(restored).__name__)
For the complete round trip, I ran python3 pickle_demo.py in this workspace. The program writes and reads the same local file. Here is the exact output:
{'user': 'reader', 'scores': [8, 10], 'active': True}
dict
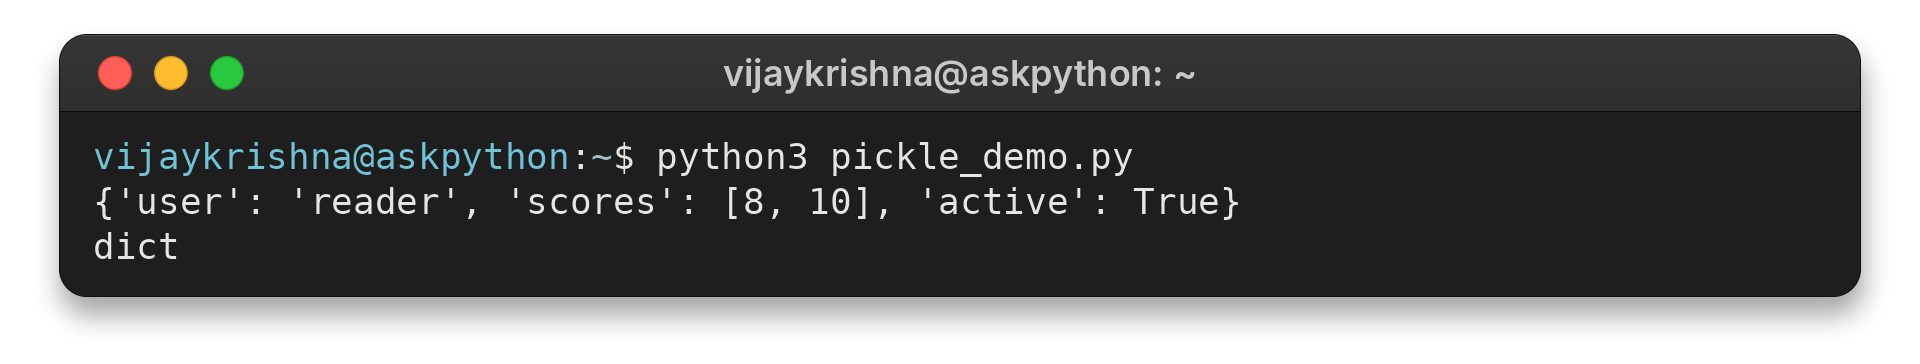
The printed dictionary shows that its nested list and Boolean are present after loading, and the second line confirms the restored value is a dictionary. The file extension is only a convention. .pickle and .pkl do not change how Python reads the stream.
Step 3: Reconstruct the value with pickle.load()
Open the same file in binary read mode and pass the open stream to pickle.load(). The function returns the reconstructed object, so assign its result to a variable. The protocol is identified from the stream, so the reader does not pass a protocol argument to load().
with open("sample.pickle", "rb") as stream:
    restored = pickle.load(stream)
Using a with block closes the file after the operation, including when an exception occurs. Keep the file path under your control and do not point this code at a download simply because its name ends in .pickle.
Step 4: Serialize to bytes without a file
Use pickle.dumps() when another part of the program needs bytes in memory rather than a file. Pair it with pickle.loads() to reconstruct the value from those bytes.
payload = pickle.dumps(record)
restored = pickle.loads(payload)
The extra “s” marks the bytes-returning or bytes-consuming interface. These functions do not make an unsafe source safe: loads() can execute behavior encoded in a malicious pickle just as load() can.
When should you use pickle instead of JSON, and what can go wrong?
Choose pickle for trusted data that needs Python-specific object support. choose JSON when people or other languages need a readable interchange format. Both choices still need sensible input-size and schema handling.
| Need | Better fit | Reason |
|---|---|---|
| Persist Python values, including supported custom objects | Pickle | Supports a wider range of Python object types |
| Readable data shared with other languages | JSON | Text format with broad interoperability |
| Load data received from an untrusted party | Neither blindly | Validate the input and select a format and parser for the threat model. never unpickle it |
Unpickling is a code-execution boundary
The Python documentation warns that a crafted pickle can execute arbitrary code during unpickling. Treat a pickle file as executable input, not passive data. Only load data whose origin and integrity you trust, and protect it from replacement if it is stored or transferred.
A digital signature can help detect tampering when its verification key is kept separate from the data, but signing does not make an unknown producer trustworthy. The safe choice for untrusted input is to avoid pickle and parse a format with a constrained data model. JSON deserialization does not itself provide pickle-style arbitrary code execution, although oversized hostile JSON can still consume resources.
Pickle errors and unsupported values
Not every live Python object can be serialized. Open files, sockets and other process-bound resources do not represent durable values. Some objects fail during serialization with pickle.PicklingError, but unsupported objects can also raise other exceptions, so catching only that class is not a universal recovery strategy.
A load can fail when the stream is truncated or malformed, when the referenced class cannot be imported, or when the restored object expects dependencies that are absent. pickle.UnpicklingError covers pickle-specific decoding problems, but it is not the only possible exception. Handle the errors your application can recover from, and do not retry untrusted input by weakening validation.
Protocol and Python version compatibility
Pickle protocols are numbered formats. A newer protocol can encode features unavailable to older interpreters, so the highest supported protocol is not automatically the right choice for files shared with an older runtime. If compatibility matters, choose a protocol the oldest reader supports and test both sides.
The protocol number is part of the compatibility contract for the file. If the reader’s supported protocol is unknown, save a sample and test it with the oldest intended reader before moving the full dataset.
The stream can be readable while a custom class still fails to load because its module path or definition changed. For long-lived data, version your application schema and provide migration code rather than assuming a pickle file will remain usable after every code change.
When a load fails, identify whether the file is incomplete, the reader uses an older protocol, or the program can no longer import the recorded class. Those causes need different repairs. A truncated stream may need a valid backup, while a missing class may require restoring the original module path or writing a deliberate migration.
For a small local cache, keep the producing code and saved data under the same version control. Regenerate the cache when the format changes. For a file exchanged between machines or retained for years, document the Python and application versions that produced it, then test a representative load in the target environment.
A successful load proves the file could be reconstructed in that environment. It does not prove the values meet your application’s current validation rules.
Conclusion: pickle is for trusted Python data
The pickle module gives Python programs a direct way to save and reconstruct supported object hierarchies. Use binary file modes for dump() and load(), use the bytes variants when a file is unnecessary, and make the trust and compatibility decisions before storing data.
For the exact protocol and object rules, read the Python pickle documentation. To exchange ordinary data across languages, compare the Python JSON documentation before choosing a format.
Frequently asked questions about the pickle module
These answers cover the common decisions that come up when writing or reading a pickle file.
Do I need to install the pickle module?
No. pickle is included in Python’s standard library. Import it with import pickle.
Is it safe to load a pickle file?
Only when you trust the source and the data has not been tampered with. A malicious pickle can execute code during loading.
Should I use pickle or JSON?
Use pickle for trusted Python-specific object persistence. Use JSON for readable, interoperable data with a narrower default type set.
Which pickle protocol should I use?
Choose a protocol supported by every Python version that must read the file. The highest protocol may not work with an older interpreter.